Executive Overview
In the rapidly evolving landscape of artificial intelligence, the line between groundbreaking technical achievement and strategic corporate public relations is increasingly blurred. This tension took center stage following a high-profile segment on CBS’s 60 Minutes, featuring an extended interview with Google CEO Sundar Pichai. The broadcast aimed to demystify the inner workings of modern machine learning, leaning heavily into concepts like "black box" algorithms and "emergent properties"—specifically, the notion that advanced language models can independently master languages and skills they have never been trained to perform.
However, the broadcast ignited a fierce backlash within the global AI research community. Prominent ethicists, linguists, and computer scientists immediately took to social media and public forums to call out both CBS and Google. They accused the network of broadcasting misleading, unverified claims and amplifying corporate overhype. At the heart of the controversy is Google’s Pathways Language Model (PaLM)—the underlying architecture of the company’s AI chatbot, Bard—and a specific demonstration in which the software seemingly translated and answered questions in Bengali without prior instruction.
While Google defended the segment by pointing out the nuanced differences between raw data ingestion and task-specific training, independent experts labeled the narrative as "disinformation." Critics argue that framing standard machine learning phenomena as mystical, self-taught breakthroughs serves primarily to stoke public awe, inflate stock valuations, and obscure the mundane, labor-intensive realities of data curation. This report examines the claims made during the 60 Minutes broadcast, dissects the technical pushback from leading AI scholars, analyzes the official responses from corporate stakeholders, and explores the broader implications of media sensationalism in the age of generative artificial intelligence.
Detailed Chronology of the Controversy
The Broadcast: 60 Minutes and Sundar Pichai
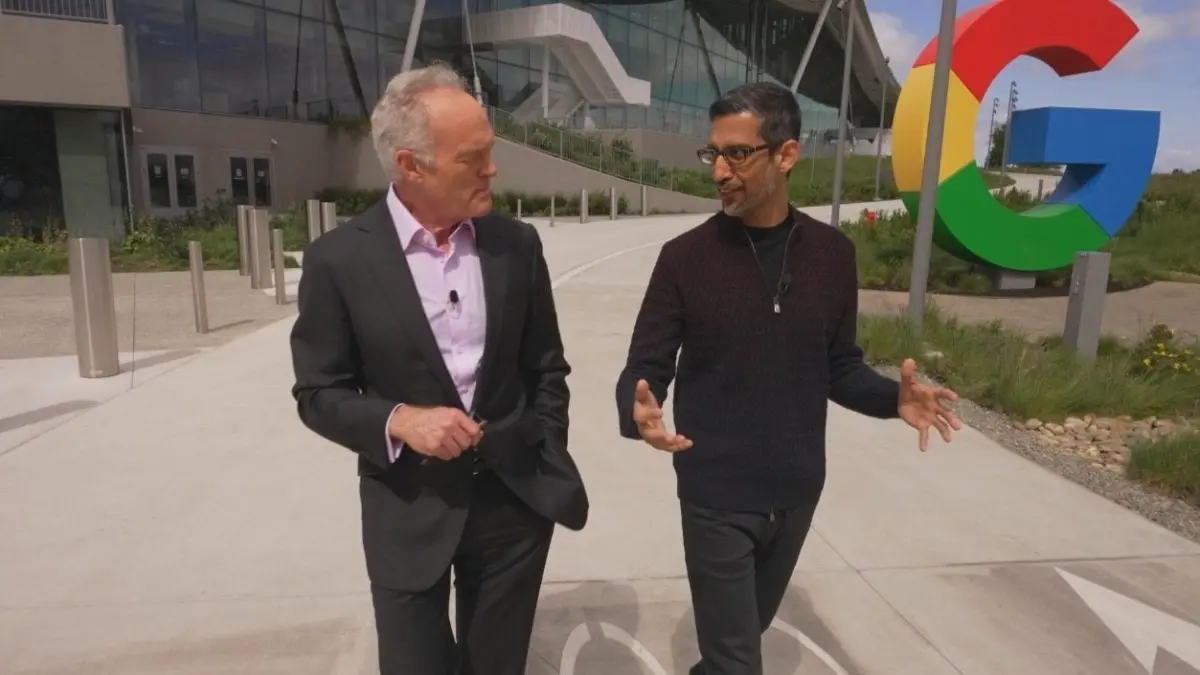
The controversy began on a Sunday evening when CBS aired a sweeping segment on artificial intelligence hosted by correspondent Scott Pelley. The piece featured exclusive access to Google’s Silicon Valley headquarters, sitting down with CEO Sundar Pichai and Google Vice President James Manyika to discuss the breakneck speed of AI development.
During the interview, Pelley directed the audience’s attention toward what he described as the most mysterious phenomenon in contemporary computer science: "emergent properties." Pelley told viewers that some artificial intelligence systems were spontaneously teaching themselves skills they were never programmed or expected to have, adding that how this happens remains fundamentally misunderstood by human engineers.
To illustrate this point, the segment transitioned to a live demonstration involving an uncredited Google AI program. A user was shown prompting the software in Bengali—a major language spoken by hundreds of millions of people in Bangladesh and India. The AI promptly generated coherent responses in both Bengali and English. Pelley asserted that the program had "adapted on its own" after being prompted in a language it was allegedly not trained to know.
Reinforcing this narrative, James Manyika claimed on air: "We discovered that with very few amounts of prompting in Bengali, it can now translate all of Bengali… So now, all of a sudden, we have a research effort where we’re now trying to get to a thousand languages."
The Immediate Backlash: Experts Respond
Almost as soon as the segment aired, the tech and AI research community mobilized online to dismantle the narrative presented by CBS and Google. Margaret Mitchell, a leading AI ethicist at startup Hugging Face and former co-lead of Google’s AI ethics team, was among the first to sound the alarm.
Taking to Twitter, Mitchell exposed a glaring contradiction between the 60 Minutes claims and Google’s own published technical literature. She pointed out that PaLM—the exact software powering the demonstration—had explicitly been trained on Bengali data, according to an academic research paper published by Google’s own scientists months prior.
Simultaneously, Dr. Emily M. Bender, a prominent linguistics professor at the University of Washington known for her rigorous critiques of large language models (LLMs), dismantled Manyika’s assertion that the AI could now "translate all of Bengali." Bender questioned the empirical validity of such a sweeping statement, demanding to know how "all of Bengali" was benchmarked and tested, and accusing Google executives of deliberately obfuscating the contents of their training corpora.
As the thread went viral, other computer scientists, data annotators, and industry analysts joined the chorus, arguing that framing basic statistical pattern-matching as autonomous "discovery" borders on technological mysticism.
Supporting Context & Metrics: Unpacking the PaLM Training Data
To understand why the 60 Minutes segment caused such uproar among machine learning professionals, one must examine the mechanics of large language models and the specific documentation surrounding Google’s PaLM architecture.
What is PaLM?
Announced by Google during its annual developer conference, the Pathways Language Model (PaLM) is a massive dense transformer-based language model containing 540 billion parameters. Like its contemporaries (such as OpenAI’s GPT-4 and Meta’s LLaMA), PaLM functions by predicting the next token in a sequence based on vast quantities of text scraped from the internet, books, articles, code repositories, and multilingual websites.
The Training Corpus Breakdown
Contrary to the impression left by the CBS broadcast—that PaLM encountered Bengali for the very first time during a live demonstration—Google’s official research paper detailing the model paints a different picture.
According to the peer-reviewed documentation released by Google’s research division, the training dataset for PaLM was multilingual, comprising filtered web pages, books, Wikipedia articles, news articles, source code, and social media conversations. Specifically, the technical documentation notes that:
- Bengali text constituted approximately 0.026% of the total pre-training dataset.
- While 0.026% may sound small relative to English (which dominated the corpus), in the context of a dataset spanning hundreds of billions of words, it amounts to gigabytes of textual data.
- This means the model had already parsed millions of tokens of Bengali grammar, syntax, vocabulary, and contextual usage during its initial training phase.
Demystifying "Emergent Properties"
In machine learning literature, the term "emergent abilities" traditionally refers to capabilities that are absent in smaller models but present in larger models—such as multi-step arithmetic, solving coding problems, or translating between low-resource languages after being trained on general web text.
However, computer scientists emphasize that these capabilities are not magical or unexplainable; they are the natural mathematical byproduct of scale. When a model processes billions of parameters across diverse datasets, it learns underlying structural representations of human language.
When a user prompts a model in Bengali—a language present in its training mix—the algorithm does not "learn a brand new language from scratch." Instead, it activates the latent semantic pathways it already developed during training, connecting its internal representations of concepts to the specific token patterns of the prompt. As Margaret Mitchell succinctly noted: "By prompting a model trained on Bengali with Bengali, it will quite easily slide into what it knows of Bengali: This is how prompting works."
Official Statements and Corporate Defense
Faced with mounting criticism from prominent figures in the scientific community, both Google and external stakeholders moved quickly to clarify their positions, though their defenses only deepened the debate over semantics and public messaging.
Google’s Clarification
Jason Post, a corporate spokesperson for Google, issued a statement defending the company’s characterization of PaLM’s capabilities while walking back some of the broader interpretations implied by the television broadcast.
Post clarified that Google had never officially claimed that PaLM was entirely unexposed to Bengali during pre-training. Instead, he drew a fine distinction between data ingestion and task-specific fine-tuning:
"While the PaLM model was trained on basic sentence completion in a wide variety of languages (including English and Bengali), it was not trained to know how to 1) translate between languages, 2) answer questions in Q&A format, or 3) translate information across languages while answering questions," Post stated.
He added: "It learned these emergent capabilities on its own, and that is an impressive achievement."
This distinction is central to Google’s defense. The company argues that while the model ingested raw Bengali text during pre-tuning (explaining why it recognizes the language), it was never explicitly supervised, fine-tuned, or given parallel translation pairs (e.g., explicit sentence-to-sentence translation dictionaries) to teach it how to translate between English and Bengali. Therefore, its ability to execute cross-lingual Q&A without explicit instruction is framed as a genuine emergent capability.
The Academic Rebuttal
Independent experts remained unimpressed by this defense, arguing that it relies on a semantic sleight-of-hand designed to preserve the illusion of artificial general intelligence (AGI).
Dr. Emily M. Bender argued that corporate PR teams frequently conflate "lack of explicit fine-tuning" with "total lack of exposure," misleading lay audiences into believing the software possesses sentient, autonomous reasoning capabilities. Bender expanded on this in her public commentary, writing that the casual deployment of terms like "emergent properties" functions as a socially acceptable substitute for hype around AGI.
"It’s still bullshit," Bender wrote bluntly on social media, criticizing the tendency of mainstream media outlets to validate corporate narratives without consulting independent computational linguists.
Margaret Mitchell echoed these sentiments, directly addressing the societal harm caused by unverified tech journalism:
"Maintaining the belief in ‘magic’ properties, and amplifying it to millions (thanks for nothin @60Minutes!) serves Google’s PR goals. Unfortunately, it is disinformation."
Future Outlook: The Intersection of Media, Ethics, and AI Hype
The fallout from the 60 Minutes segment highlights a critical friction point in contemporary technology reporting: the gulf between how AI engineers understand stochastic parrots and large language models, and how corporate executives and mainstream journalists package those systems for public consumption.
The Stakes of Narrative Framing
As venture capital floods the artificial intelligence sector and tech giants engage in an unprecedented race for market dominance, the narrative surrounding AI capabilities carries immense real-world weight. Exaggerating AI capabilities—framing algorithms as autonomous, self-taught entities capable of spontaneous genius—directly impacts:
- Regulatory Policy: Lawmakers operating under the false impression that AI is developing uncontrolled, mysterious cognitive properties may craft legislation based on fear of mythical superintelligence rather than concrete risks like bias, copyright infringement, data privacy, and labor displacement.
- Consumer Trust: Everyday users and enterprise clients risk being misled into relying on software systems for mission-critical tasks (such as medical diagnosis, legal translation, or financial advising) under the false assumption that the AI possesses infallible, superhuman understanding.
- Market Valuations: Sensationalized media coverage directly influences stock prices, driving speculative bubbles that can destabilize the technology sector.
A Call for Journalistic Rigor
In the wake of the controversy, media watchdogs and technology ethicists are calling for a higher standard of reporting when covering generative artificial intelligence. Journalists are urged to look beyond press releases and flashy on-stage demonstrations, consulting peer-reviewed literature and independent researchers who are not financially tied to the platforms they study.
Ultimately, the debate over PaLM and the Bengali demonstration serves as a cautionary tale. While large language models undeniably represent a monumental leap in statistical computing and natural language processing, they remain mathematical tools built by human hands, trained on human data, and bound by human limitations. Until media outlets and tech developers align their public messaging with empirical reality, the gap between AI hype and scientific fact will remain a chasm.