Executive Overview
The intersection of mainstream journalism and cutting-edge artificial intelligence recently produced a major flashpoint. Following a high-profile segment on CBS’s 60 Minutes featuring Google CEO Sundar Pichai, leading AI researchers and ethicists have fiercely criticized both the network and the tech giant for overhyping artificial intelligence capabilities.
At the heart of the controversy was a narrative promoted during the broadcast: that a Google AI model had mysteriously taught itself a language it had never seen before—an example of so-called "emergent properties" where software allegedly develops unprogrammed, autonomous skills.
However, prominent AI scientists swiftly pushed back against this framing, pointing out that the language in question, Bengali, was explicitly included in the model’s training data. Critics argue that presenting standard machine learning mechanics as magical, spontaneous breakthroughs is a form of corporate public relations designed to inflate hype, deflect accountability, and obscure the deterministic nature of large language models (LLMs). This incident has renewed intense debates regarding media literacy, responsible AI reporting, and the ethical responsibilities of tech executives when communicating with the global public.
Detailed Chronology of the Controversy
The Broadcast: 60 Minutes and the "Black Box" of AI
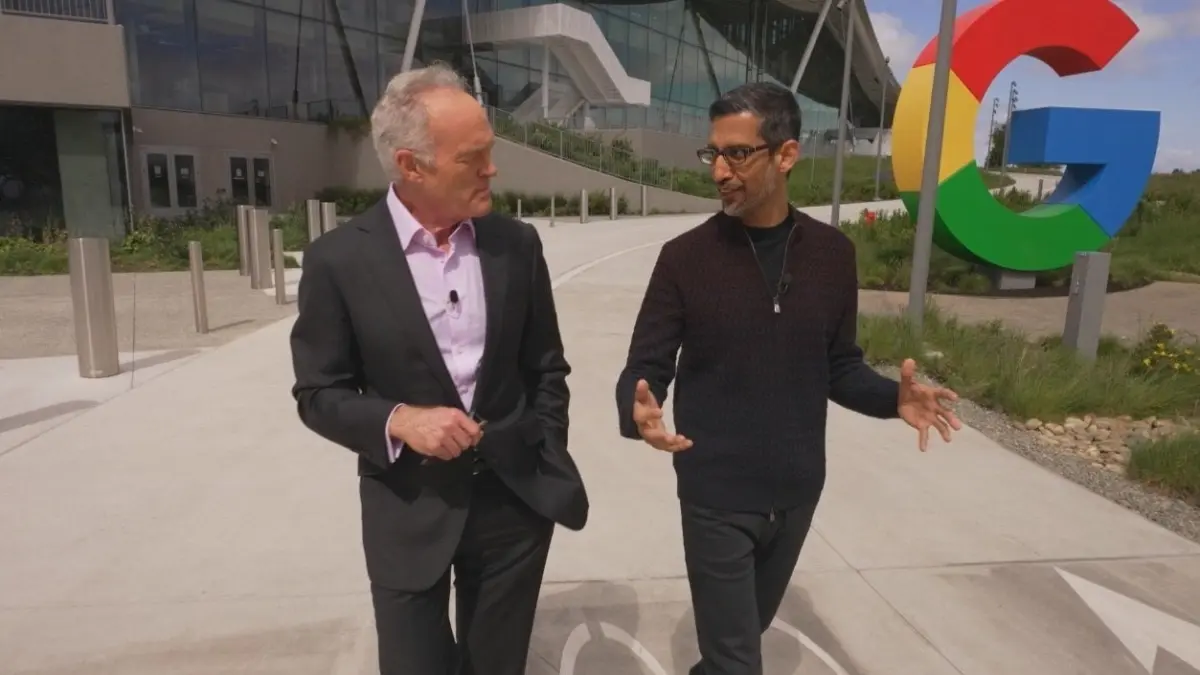
On a Sunday evening broadcast, CBS’s 60 Minutes aired an ambitious segment exploring the rapid evolution, immense promise, and latent dangers of artificial intelligence. Correspondent Scott Pelley guided viewers through Google’s sprawling Mountain View campus, interviewing key executives, including CEO Sundar Pichai and Google Senior Vice President James Manyika.
Throughout the segment, the tone leaned heavily into the mystical and the incomprehensible. Pichai referred to AI technology as a "black box," suggesting that even the engineers and researchers who build and deploy these systems do not fully understand how they function under the hood.
Pelley amplified this sense of wonder by focusing on what he termed "emergent properties."
"Of the AI issues we talked about, the most mysterious is called ‘emergent properties,’" Pelley told viewers. "Some AI systems are teaching themselves skills that they aren’t expected to have. How this happens is not well understood."
To illustrate this phenomenon, the segment featured a demonstration of an unidentified Google AI program. A user prompted the system in Bengali—a language predominantly spoken in Bangladesh and India—and the software seamlessly responded in both Bengali and English. Pelley claimed that the software had "adapted on its own" after being exposed to a language it was never trained to know.
Echoing this narrative, James Manyika stated on air:
"We discovered that with very few amounts of prompting in Bengali, it can now translate all of Bengali. So now, all of a sudden, we have a research effort where we’re now trying to get to a thousand languages."
The Backlash: Researchers Call Out Misinformation
Almost immediately after the segment aired, the tech research community took to social media to dismantle the claims made by CBS and Google.
Margaret Mitchell, a prominent AI researcher, ethicist at startup Hugging Face, and former co-lead of Google’s AI ethics team, took to Twitter to point out a glaring discrepancy. Mitchell noted that the software demonstrated in the segment was PaLM (Pathways Language Model)—the underlying architecture powering Google’s AI chatbot, Bard.
According to Google’s own technical documentation and research papers published prior to the broadcast, Bengali was unequivocally part of PaLM’s training corpus. Specifically, Google’s published research paper on PaLM indicates that Bengali constituted approximately 0.026% of the model’s massive multi-lingual training dataset.
Mitchell wrote on Twitter:
"By prompting a model trained on Bengali with Bengali, it will quite easily slide into what it knows of Bengali: This is how prompting works."
She added that it is fundamentally impossible for an artificial intelligence model to "speak well-formed languages that you’ve never had access to."
The Defense: Google Clarifies Its Stance
As the criticism mounted, Google representatives defended the company’s messaging while attempting to thread the needle between corporate marketing and technical reality.
Jason Post, a corporate spokesperson for Google, told reporters that the company had never officially claimed it did not train PaLM on Bengali text. Instead, Post refined the definition of what Google meant by the software’s autonomous learning:
"While the PaLM model was trained on basic sentence completion in a wide variety of languages (including English and Bengali), it was not trained to know how to 1) translate between languages, 2) answer questions in Q&A format, or 3) translate information across languages while answering questions," Post stated. "It learned these emergent capabilities on its own, and that is an impressive achievement."
This distinction attempts to pivot the argument from data exposure to task capability. Google argues that while the model had seen raw Bengali text during tokenization and pre-training (for basic web-scale text prediction), it was never explicitly fine-tuned or supervised for translation tasks or question-answering pairs in that specific language.
Amplified Critique: Academic Pushback
The defense did little to appease academic researchers. Dr. Emily M. Bender, a linguistics professor and researcher at the University of Washington known for her rigorous critiques of LLM hype, dismantled James Manyika’s assertion that PaLM could now translate "all of Bengali."
In a blistering Twitter thread and subsequent interviews, Bender challenged the scientific rigor of Manyika’s claims:
"What does ‘all of Bengali’ actually mean? How was this tested?" Bender asked, noting that statements of this scale are entirely unscoped and unsubstantiated. Furthermore, she argued that Manyika’s framing deliberately concealed the presence of Bengali text in the model’s training data to manufacture a narrative of spontaneous, miraculous evolution.
Bender also took direct aim at the overuse of the term "emergent properties" in modern AI discourse:
"The term ‘emergent properties’ seems to be the respectable way of saying AGI [Artificial General Intelligence]. It’s still bullshit."
Margaret Mitchell echoed these sentiments, condemning the broadcast as corporate public relations disguised as objective journalism:
"Maintaining the belief in ‘magic’ properties, and amplifying it to millions (thanks for nothin @60Minutes!) serves Google’s PR goals. Unfortunately, it is disinformation."
Supporting Context & Metrics: Deconstructing PaLM and Training Data
To understand why researchers reacted so vehemently to the 60 Minutes segment, it is necessary to examine the technical foundations of modern Large Language Models (LLMs) like Google’s PaLM.
What is PaLM?
Introduced by Google in April 2022, the Pathways Language Model (PaLM) is a 540-billion parameter dense decoder-only transformer model. Designed to scale across thousands of TPU chips, PaLM was trained on a massive, highly diverse corpus comprising web pages, books, Wikipedia articles, news stories, and source code.
The Reality of Multilingual Training Data
Modern LLMs are not taught languages the way human students are in a classroom. They do not receive explicit grammar lessons, vocabulary lists, or bilingual dictionaries. Instead, they ingest vast oceans of text scraped from the public internet.
Because the internet is predominantly written in English, high-resource languages like English, Spanish, and French make up the vast majority of training datasets. However, web crawlers also capture significant amounts of text in low-resource or mid-resource languages, including Bengali, Swahili, and Vietnamese.
| Metric / Parameter | Google PaLM Specifications |
|---|---|
| Total Parameters | 540 Billion |
| Training Dataset Composition | Multilingual web text, books, Wikipedia, news, source code |
| Bengali Training Share | ~0.026% of total pre-training corpus |
| Explicit Task Training | Pre-trained on raw text prediction; not explicitly fine-tuned for supervised translation |
When a model like PaLM processes a text dataset, it breaks words down into smaller sub-units called "tokens." Even if a language like Bengali makes up a fraction of a percent of the overall training data—in this case, roughly 0.026%—that fraction still amounts to millions of individual words and sentence structures.
When a user prompts the model in Bengali, the system does not magically invent a new linguistic system out of thin air. Rather, it activates the statistical patterns, associations, and probabilistic weight distributions it absorbed during its initial web-scraping phase. It recognizes the patterns of the Bengali script and maps them against its internal multilingual vector space, allowing it to generate coherent continuations or responses.
Official Statements and Industry Reactions
The fallout from the 60 Minutes segment highlights a deep and growing rift between commercial AI developers striving for market dominance and the scientific community advocating for transparency, accuracy, and ethical communication.
The Corporate Perspective: Driving Innovation and Acknowledging Novelty
Google maintains that the transition from raw text prediction to multi-tasking capabilities across unseen task formats represents a genuine leap forward in machine learning engineering. Executives argue that while the underlying data was technically present in the training set, the model’s ability to synthesize that data to perform complex translation and question-answering without explicit supervision is what warrants the label of an "emergent property."
In corporate communications, framing these milestones as awe-inspiring breakthroughs helps secure investor confidence, drive consumer adoption of products like Google Bard, and position the company as a pioneering leader in the race toward artificial general intelligence.
The Scientific Perspective: Combatting the "Magic" Narrative
Conversely, independent researchers and ethicists argue that leaning into mystical framing—portraying AI as an autonomous entity with a mysterious, inscrutable mind—carries profound societal risks.
- Accountability Deflection: If an AI system is perceived as a "black box" that acts unpredictably and learns entirely on its own, developers and corporations can more easily evade responsibility when those systems fail, hallucinate, spread hate speech, or violate intellectual property rights.
- Misinforming the Public: When mainstream media outlets broadcast unverified or exaggerated claims about AI capabilities to millions of viewers, it creates widespread societal panic or misplaced techno-optimism. Policymakers trying to regulate the industry are left reacting to myth rather than empirical reality.
- Diluting Scientific Rigor: Researchers spend years attempting to demystify neural networks through interpretability research. Conflating standard probabilistic pattern-matching with spontaneous consciousness or unguided skill acquisition undermines rigorous scientific inquiry.
Future Outlook: The Path Forward for AI Reporting and Governance
The controversy surrounding the Google and CBS collaboration serves as a cautionary tale for both the technology sector and mainstream journalism. As artificial intelligence continues to dominate public discourse, the demand for clear, sober, and scientifically accurate reporting has never been more urgent.
1. Reforming Media Literacy in Tech Coverage
Major news organizations must elevate their internal technical literacy or consult independent, objective domain experts before broadcasting claims about AI breakthroughs. Hype-driven narratives that personify software or frame algorithms as magical entities do a disservice to the public. Future journalism must focus on the mechanics of data collection, algorithmic design, and the socio-economic impacts of deployment rather than speculative mysticism.
2. Greater Transparency from Big Tech
Calls for transparency in AI development are growing louder. Regulators in the European Union, the United States, and elsewhere are pushing for mandatory disclosures regarding training datasets, energy consumption, and model limitations. Companies like Google, OpenAI, and Anthropic will face increasing pressure to publish detailed data sheets and model cards that clearly outline what their systems have ingested and how they process information.
3. Collaborative Oversight
Bridging the gap between corporate marketing departments and academic research institutions is essential. For artificial intelligence to mature safely and equitably, the narrative surrounding its capabilities must be grounded in empirical facts, moving away from hyperbolic PR stunts and toward responsible, transparent stewardship of transformative technologies.