Executive Overview
The intersection of artificial intelligence and mainstream media reached a flashpoint following a high-profile segment on CBS’s 60 Minutes featuring Google CEO Sundar Pichai. The broadcast, designed to demystify the rapidly advancing frontier of machine learning, instead triggered a fierce backlash from the global AI research community.
At the heart of the controversy was a narrative pushed by both the network and Google executives: that a proprietary AI system had spontaneously learned a language it had never been exposed to—a phenomenon framed as a mysterious "emergent property" bordering on artificial general intelligence (AGI).
However, prominent AI ethicists, data scientists, and computational linguists quickly dismantled these claims. Pointing directly to Google’s own technical documentation, critics demonstrated that the model in question—PaLM, the foundational technology powering Google’s Bard chatbot—had indeed been trained on text corpora containing the language in question, Bengali.
What the network and Google framed as spontaneous linguistic acquisition was, in reality, standard probabilistic pattern-matching: an AI utilizing its pre-existing training data to respond to prompts in a language it had already ingested.
This incident exposes a deepening rift between corporate public relations strategies and scientific integrity. As tech giants race for market dominance in the generative AI space, the temptation to sensationalize technological milestones—transforming incremental engineering feats into mystical leaps of machine consciousness—poses a significant risk to public understanding.
This report provides an in-depth examination of the 60 Minutes broadcast, the technical realities of PaLM, the public outcry from the scientific community, and the broader implications of hyping artificial intelligence for mainstream consumption.
Detailed Chronology
The Broadcast: 60 Minutes and the "Black Box" Narrative
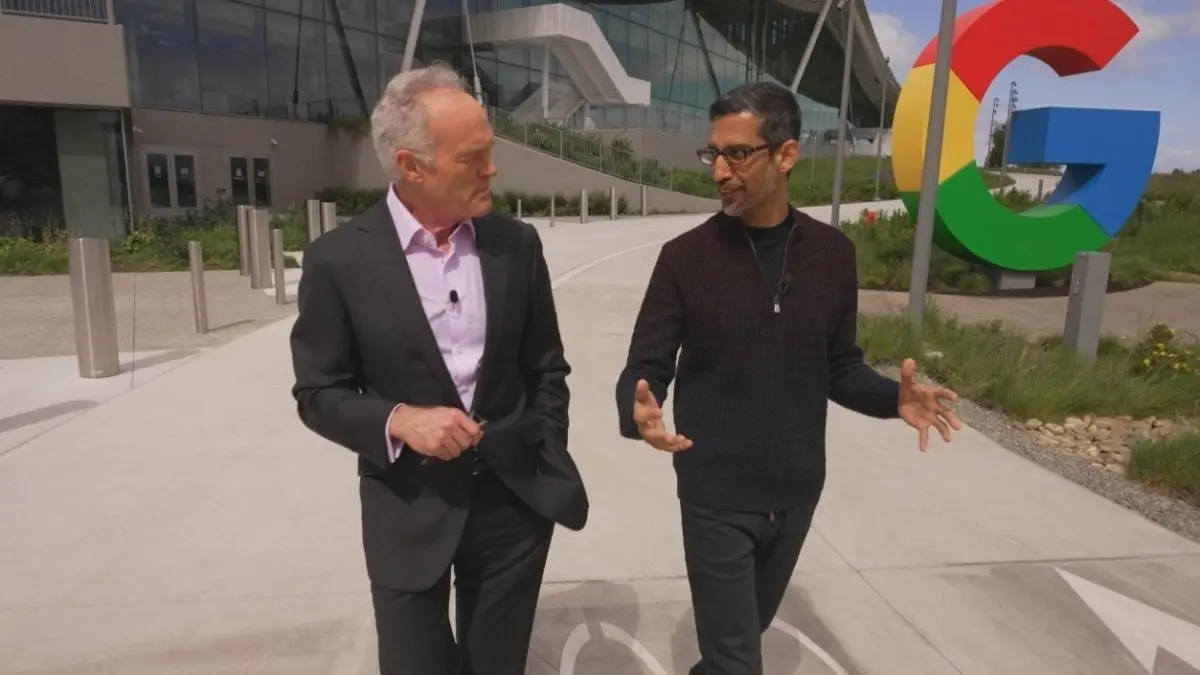
On a Sunday evening, millions of viewers tuned into CBS’s 60 Minutes to watch veteran correspondent Scott Pelley interview Google CEO Sundar Pichai. The segment aimed to explore the dizzying pace of AI development, focusing heavily on the opaque nature of modern neural networks. Pichai described AI as a "black box," suggesting that even its creators do not fully understand how deep learning models arrive at their conclusions.
Pelley introduced viewers to what he termed the most mysterious concept in modern computing: "emergent properties."
"Some AI systems are teaching themselves skills that they aren’t expected to have," Pelley told the audience. "How this happens is not well understood."
To illustrate this point, the segment cut to a live demonstration of an uncredited Google AI program. A user entered questions in Bengali—a language spoken by over 260 million people primarily in Bangladesh and the Indian subcontinent—and the software generated fluent responses in both Bengali and English.
Pelley asserted that the program had "adapted on its own" after being prompted in Bengali, a language he claimed the system was fundamentally "not trained to know."
Reinforcing this narrative, James Manyika, a Google senior vice president also interviewed for the segment, claimed:
"We discovered that with very few amounts of prompting in Bengali, it can now translate all of Bengali. So now, all of a sudden, we have a research effort where we’re now trying to get to a thousand languages."
The Backlash: Researchers Call Out Misinformation
Almost immediately after the broadcast aired, independent AI researchers and ethicists took to social media to challenge the factual accuracy of the segment. The narrative of an AI spontaneously inventing or acquiring a language out of thin air directly contradicted foundational principles of natural language processing (NLP).
Margaret Mitchell, a leading AI ethicist at startup Hugging Face and the former co-lead of Google’s AI ethics team, led the charge on Twitter. Mitchell pointed out that the software demonstrated in the segment was PaLM (Pathways Language Model), the same architecture underlying Google’s chatbot, Bard.
More importantly, Mitchell cited Google’s own research paper on PaLM, published by its engineering teams, which explicitly details the composition of the model’s training data.
According to the official PaLM technical paper, Bengali text comprised approximately 0.026% of the model’s massive multilingual training corpus.
"By prompting a model trained on Bengali with Bengali, it will quite easily slide into what it knows of Bengali: This is how prompting works," Mitchell tweeted.
She added that it is fundamentally impossible for a machine learning model to "speak well-formed languages that you’ve never had access to."
Google’s Defense and Clarification
As public criticism mounted, tech media outlets sought clarification from Google representatives. Jason Post, a company spokesperson, offered a statement that walked back the absolutist framing presented on television, while still defending the core engineering achievement.
Post clarified that Google had never claimed it omitted Bengali from the training data entirely. Instead, he argued that the model’s true breakthrough lay in its zero-shot transfer capabilities:
"While the PaLM model was trained on basic sentence completion in a wide variety of languages (including English and Bengali), it was not trained to know how to 1) translate between languages, 2) answer questions in Q&A format, or 3) translate information across languages while answering questions," Post stated. "It learned these emergent capabilities on its own, and that is an impressive achievement."
However, this distinction did little to appease researchers who argued that the damage had already been done by the original framing on 60 Minutes, which implied the AI had learned the language without any prior exposure.
Supporting Context & Metrics
To understand why the 60 Minutes segment caused such uproar within the technical community, it is necessary to examine the architecture of Large Language Models (LLMs) and the specific metrics surrounding the PaLM system.
Dissecting the PaLM Training Corpus
The Pathways Language Model (PaLM), introduced by Google in April 2022, is a 540-billion-parameter dense decoder-only transformer model. Training a model of this scale requires ingesting petabytes of text data harvested from the internet, including filtered web pages, books, Wikipedia articles, news sources, and source code.
- Multilingual Breakdown: The PaLM training dataset comprised a massive multilingual corpus covering hundreds of languages. While English dominated the dataset (representing roughly 78% of the data), low-resource languages—including Bengali, Tamil, and Swahili—were included in fractional amounts.
- Bengali’s Share: Bengali made up roughly 0.026% of the total training tokens. While small relative to English, 0.026% of a training corpus comprising hundreds of billions of words amounts to millions of individual tokens of Bengali text.
- Exposure vs. Instruction: The model was exposed to raw Bengali text during unsupervised pre-training (predicting the next token in a sequence). It was not explicitly fine-tuned via supervised learning to act as a conversational assistant or translator in Bengali.
What is an "Emergent Property" in AI?
In the lexicon of machine learning, "emergent properties" refer to capabilities that are not explicitly programmed into a model during its design phase but appear as the model scales in size and computational power. For example, a smaller language model might struggle with multi-step arithmetic, whereas a 540-billion-parameter model like PaLM can perform rudimentary math—not because it was taught a calculator algorithm, but because mathematical patterns emerge from processing vast amounts of text.
However, computational linguists argue that applying the term "emergent" to language acquisition is misleading.
- Pattern Matching, Not Magic: LLMs do not "learn" languages the way humans do. They map statistical relationships between words and tokens. If a model has processed millions of Bengali tokens, it possesses an internal vector space representing Bengali syntax and semantics. When prompted in Bengali, it simply activates those pre-existing pathways.
- The "AGI" Slip: Critics like University of Washington professor Emily M. Bender argue that corporate PR teams and media outlets use terms like "emergent properties" as a sanitized proxy for Artificial General Intelligence (AGI)—the holy grail of AI research denoting sentient, human-level intelligence.
Official Statements & Industry Reactions
The controversy drew sharp rebukes from prominent figures across the artificial intelligence and linguistic research communities, who accused both CBS and Google of fostering dangerous misconceptions.
Professor Emily M. Bender (University of Washington)
Emily M. Bender, a vocal critic of AI hype and co-author of foundational papers on the risks of stochastic parrots, took direct aim at Google Vice President James Manyika’s claim that PaLM could suddenly translate "all of Bengali."
"What does ‘all of Bengali’ actually mean? How was this tested?" Bender asked in a widely shared Twitter thread.
She accused Google of obfuscating the presence of Bengali text in their training data to manufacture a sense of technological awe.
"The term ’emergent properties’ seems to be the respectable way of saying AGI," Bender wrote. "It’s still bullshit."
Margaret Mitchell (Hugging Face)
Margaret Mitchell emphasized that framing routine machine learning mechanics as magical breakthroughs serves corporate bottom lines at the expense of public literacy.
"Maintaining the belief in ‘magic’ properties, and amplifying it to millions (thanks for nothin @60Minutes!) serves Google’s PR goals," Mitchell tweeted. "Unfortunately, it is disinformation."
Google’s Official Stance
Google maintains that while the terminology used in the broadcast may have been compressed for television, the underlying technological milestone remains valid. Company representatives argue that moving from static next-token prediction to cross-lingual question-answering without explicit task-specific fine-tuning represents a genuine leap in model generalization.
Future Outlook
The CBS-Google controversy highlights a critical challenge for the artificial intelligence industry as it transitions from academic research labs to mainstream consumer products. As tech giants compete fiercely for dominance in the generative AI market—pitting Google’s Bard and Gemini against OpenAI’s ChatGPT and Microsoft’s Copilot—the pressure to generate sensational headlines has never been higher.
The Dangers of AI Mysticism
When media outlets and tech executives frame machine learning models as autonomous, quasi-sentient entities capable of spontaneous miracles, several negative consequences ensue:
- Misinformed Policy and Regulation: Lawmakers attempting to regulate AI safety may base their policies on exaggerated claims of machine consciousness rather than the mundane reality of algorithmic data processing and copyright infringement.
- Erosion of Public Trust: When consumers are led to believe an AI has mysteriously "taught itself" a language, subsequent revelations that the data was present in the training set lead to widespread cynicism and accusations of dishonesty.
- Misallocation of Resources: Mystifying AI mechanics distracts from real, pressing ethical issues—such as data privacy, labor exploitation in data labeling, bias amplification, and environmental carbon footprints.
Moving Toward Transparent Journalism
Moving forward, tech journalism must adopt a more critical, scientifically rigorous approach when covering artificial intelligence. Rather than accepting corporate demonstrations at face value, reporters must interrogate underlying training methodologies, dataset compositions, and engineering constraints.
Until the gap between marketing hype and engineering reality is bridged, controversies like the 60 Minutes Bengali debacle will continue to serve as cautionary tales about the perils of overhyping the machine.