Executive Overview
When OpenAI launched ChatGPT in November 2022, it triggered a paradigm shift across the global technology ecosystem. Seemingly overnight, large language models (LLMs) transitioned artificial intelligence from a specialized academic discipline into an ubiquitous, consumer-facing utility. Text generation, code writing, and image synthesis rapidly scaled across consumer software, unlocking billions of dollars in enterprise value.
Yet, as conversational AI accelerates across digital platforms, a fundamental hardware-software disconnect persists in the physical realm. Robotics—despite decades of industrial deployment, mechanical refinement, and venture capital investment—has yet to experience its equivalent breakthrough moment. General-purpose physical robots capable of seamlessly understanding, navigating, and manipulating unstructured, real-world environments remain largely confined to pilot programs and laboratory demonstrations.
The primary obstacle preventing physical AI from replicating generative AI’s explosive trajectory is structural: the lack of a unified, web-scale physical dataset. While software-based LLMs were trained on trillions of text tokens harvested from decades of public internet archiving, physical AI lacks a standardized repository for spatial dynamics, gravity, friction, and multi-modal sensory inputs.
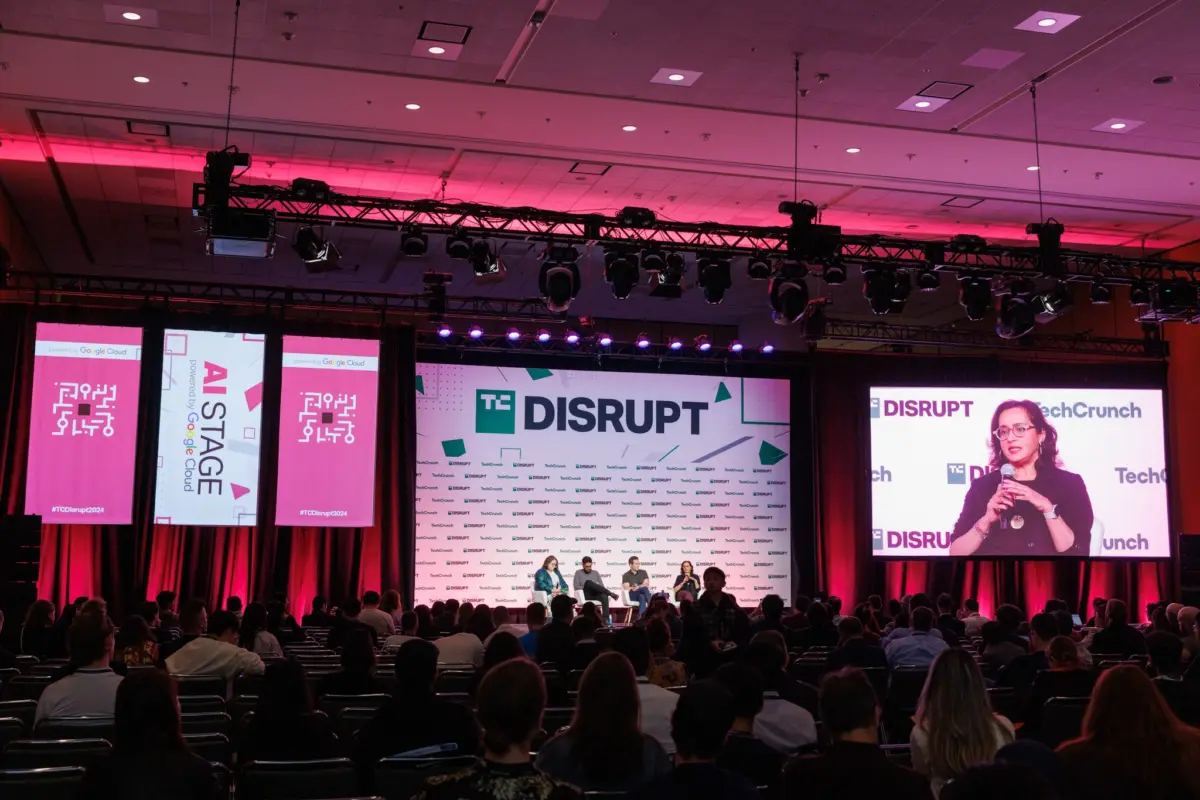
At TechCrunch Disrupt 2026, scheduled for October 13–15 at San Francisco’s Moscone West, Les Karpas, Global Head of Physical AI at Nvidia Inception, will deliver a keynote address on the Real World AI Stage titled "Robots Are Waiting for Their ChatGPT Moment. Here Is What Is Standing in the Way." Karpas will detail how the tech industry is engineering synthetic workarounds, leveraging physics engines, and deploying physical foundation models to bridge this digital-to-physical divide.
Detailed Chronology: From Digital Tokens to Physical Actuators
  +---------------------------------------------------------------------------------+
  |                             EVOLUTION OF AI MODELS                              |
  +---------------------------------------------------------------------------------+
  |  2017–2021: Digital Token Era                                                   |
  |  - Transformer Architecture introduced (Vaswani et al.)                           |
  |  - Training on web-scale text (Common Crawl, Wikipedia, GitHub)                  |
  |                                                                                 |
  |  NOV 2022: The Generative Inflection Point                                      |
  |  - ChatGPT debuts; consumer AI scale reached via text/image interfaces           |
  |                                                                                 |
  |  2015–2025: Autonomous Vehicle Data Gathering                                  |
  |  - Waymo & Tesla accumulate millions of road-driven miles                      |
  |  - High cost, hyper-specialized data (limited to 2D/3D driving geometry)         |
  |                                                                                 |
  |  2024–2026+: The Embodied AI Frontier                                           |
  |  - Rise of Physical Foundation Models (Project GR00T, RT-2)                      |
  |  - High-fidelity synthetic simulation & digital twins bridge the scale gap      |
  +---------------------------------------------------------------------------------+
The 2022 Generative Breakthrough
The breakthrough of natural language processing relied on two decades of accumulated open-source data. The deployment of the Transformer architecture in 2017 allowed models to process vast corpora of unstructured text simultaneously. When OpenAI released ChatGPT in late 2022, the underlying foundation models had already parsed virtually the entirety of digitized human text—spanning Wikipedia, open-source software codebases, academic literature, and digitized media.
The Autonomous Vehicle Precedent
The closest historical antecedent to physical AI data accumulation occurred within the autonomous vehicle (AV) sector. Beginning in the mid-2010s, companies like Waymo, Cruise, and Tesla deployed sensor-laden vehicle fleets to collect real-world driving data. While successful in creating localized, domain-specific autonomous capabilities, this approach underscored the vast resources required to train physical models:
- Capital Intensity: Billions of dollars spent operating physical fleets.
- Narrow Application: Data collected by a four-wheeled vehicle moving on paved roads does not translate to a two-legged humanoid picking up fragile objects in a warehouse or a multi-axis arm operating on a factory floor.
The Emergence of Physical Foundation Models (2024–2026)
Between 2024 and 2026, the artificial intelligence industry began pivoting toward "Embodied AI"—integrating neural networks directly into physical hardware. Frameworks such as Google’s RT-2, Nvidia’s Project GR00T, and specialized architectures from startups like Figure AI introduced multimodal vision-language-action (VLA) models. These systems attempt to parse textual instructions, synthesize visual inputs, and execute real-time physical motor controls.

However, scaling these physical models continues to run into hardware limitations, sensor noise, and a severe deficit of real-world interaction data.
Supporting Context & Metrics: The Asymmetry in Data Scale
The operational bottleneck facing general-purpose robotics becomes clear when comparing training inputs across digital and physical domains.
| Metric / Dimension | Digital Generative AI (LLMs / Multimodal) | Physical AI & Robotics |
|---|---|---|
| Primary Training Medium | Text tokens, static pixels, code repos | Kinematic trajectories, force sensors, depth maps, contact dynamics |
| Data Sourcing | Web-scale scraping (Common Crawl, Reddit, open books) | Teleoperation, physical real-world trials, synthetic simulation |
| Scale of Training Corpus | 10+ Trillion Tokens | Estimated < 100,000 Hours of high-quality teleoperated physical data |
| Cost per Data Point | Negligible (Digital bandwidth & storage) | High (Requires human operator, physical hardware wear-and-tear) |
| Iteration Speed | Limited only by GPU compute availability | Constrained by real-time physics (1 second in reality = 1 second of data) |
| Failure Cost | Hallucinated text, minor rendering errors | Physical damage to hardware, facility hazards, safety risks |
The "Sim-to-Real" Transfer Gap
To overcome the physical speed limits of data collection, roboticists rely heavily on simulation environments. By constructing digital twins inside physics engines—such as Nvidia Isaac Sim—engineers can run thousands of virtual robots concurrently, generating millions of hours of synthetic interaction data per day.
       +-------------------------------------------------------------+
       |                  THE SIM-TO-REAL PIPELINE                   |
       +-------------------------------------------------------------+
       |  1. SYNTHETIC GENERATION                                    |
       |     Nvidia Isaac Sim / Digital Twins                        |
       |     (Simulates 100,000+ virtual training hours daily)       |
       |                              |                              |
       |                              v                              |
       |  2. DOMAIN RANDOMIZATION                                    |
       |     Randomizing lighting, friction, motor resistance,       |
       |     and object textures to prevent overfitting              |
       |                              |                              |
       |                              v                              |
       |  3. PHYSICAL DEPLOYMENT                                     |
       |     Zero-Shot / Few-Shot transfer to real-world hardware    |
       |     (Addressing sensor noise, latency, and material wear)   |
       +-------------------------------------------------------------+
While synthetic data solves the sheer volume problem, it introduces the sim-to-real gap: subtle discrepancies between simulated physics and physical reality—such as microscopic material friction, thermal expansion, sensor latency, and gear backlash—can cause models that perform perfectly in software to fail in real-world application.
Official Statements and Industry Perspectives
Les Karpas on the Physical Data Void
Les Karpas, Global Head of Physical AI at Nvidia Inception, highlights that the fundamental bottleneck in robotics is not a lack of compute or neural architecture design, but rather the absence of broad physical datasets:
"Nobody has an internet-wide dataset for physical AI in the way OpenAI, Anthropic, and others had for language," notes Karpas regarding the challenge. "Even self-driving fleets were able to build datasets through years of accumulated road miles. A growing ecosystem of startups is now trying to manufacture that scale artificially through simulation, synthetic data, and foundation models trained across many robot forms simultaneously."
Karpas’s background spans an array of physical engineering, venture capital, and cross-disciplinary leadership roles, including executive positions at Stanley Black & Decker, iRobot, Herman Miller, Intellectual Ventures, and Cirque du Soleil. His group within Nvidia Inception engages with thousands of early-stage startups across robotics, automotive engineering, industrial automation, and smart infrastructure.

Nvidia’s Executive Outlook
Nvidia Chief Executive Officer Jensen Huang has repeatedly emphasized that the next frontier of artificial intelligence lies in physical systems that understand the laws of physics. During recent keynotes, Huang framed physical AI as a trillion-dollar market opportunity, positioning Nvidia’s Omniverse ecosystem and specialized chips as the core infrastructure required to simulate real-world environments before physical deployment.
Cross-Sector Voices at TechCrunch Disrupt 2026
The discussion around embodied AI on the Real World AI Stage at Moscone West will expand beyond industrial manipulation to include leaders across defense, biology, and developer tools:
- Shield AI: Focused on autonomous defense systems capable of operating without GPS or external communications in contested airspace.
- Foxglove: Developing robotics observability and telemetry visualization tools to manage real-time physical fleets.
- FieldAI: Building foundation models that enable uncrewed systems to navigate unmapped, unstructured terrestrial environments.
- Colossal Biosciences: Applying robotics and high-throughput automation to bioengineering and genetic restoration.
Future Outlook: Unlocking the Next Inflection Point
As the robotics sector moves toward its breakthrough moment, key technical developments are beginning to converge, setting the stage for a dramatic acceleration between 2026 and 2030.
  PHYSICAL AI MATURITY ROADMAP

  [ Phase 1: Isolated Automation ] ------------------------------------+
  * Rigid scripting, fixed factory arms, controlled conditions         |
                                                                       v
  [ Phase 2: Domain-Specific Autonomy ] -------------------------------+
  * Autonomous warehouse AGVs, self-driving cars, vacuum robots        |
                                                                       v
  [ Phase 3: Simulated Foundation Models ] <--- CURRENT STAGE ---------+
  * Sim-to-real transfer, synthetic data, zero-shot basic tasking      |
                                                                       v
  [ Phase 4: General-Purpose Physical AI ] ----------------------------+
  * Cross-embodiment foundation models, real-time dexterity, broad task generality
Key Technical Accelerators
- Domain Randomization & Neural Rendering: Advanced neural rendering techniques allow simulation engines to dynamically alter lighting, material textures, and object masses, conditioning foundation models to remain resilient against physical variations.
- Standardized Teleoperation Hardware: The proliferation of low-cost, high-precision teleoperation rigs enables human operators to collect real-world demonstration data rapidly, feeding centralized physical foundation models.
- Cross-Embodiment Training: Emerging architecture designs allow a single foundation model to be trained simultaneously on dynamic humanoid bipeds, four-legged quadrupeds, multi-axis industrial arms, and wheeled mobile manipulators.
Experiencing the Physical AI Debate at TechCrunch Disrupt 2026
The structural challenges, breakthroughs, and venture opportunities defining physical AI will take center stage at TechCrunch Disrupt 2026, hosted at San Francisco’s Moscone West from October 13–15.
Attendees will gain direct access to insights from Nvidia’s Les Karpas alongside over 10,000 tech leaders, founders, and venture capitalists. The event features dedicated tracks spanning startup building, deep tech innovation, and physical AI integration.
- Early-Bird Registration: Attendees who register before September 25 can save up to $200 on individual passes.
- Group Discounting: Enterprise teams, founder cohorts, and investment groups can access savings of up to 30% through bundle registration packages.
As physical AI moves closer to resolving its data scaling bottlenecks, the strategies discussed at events like TechCrunch Disrupt will define which platform providers, hardware developers, and software architects successfully usher in the physical world’s "ChatGPT moment."